Rankera / llms.txt case study
llms.txt case study · 517 websites · 17 to 23 Oct 2026
llms.txt vs .md files: what AI crawlers actually read
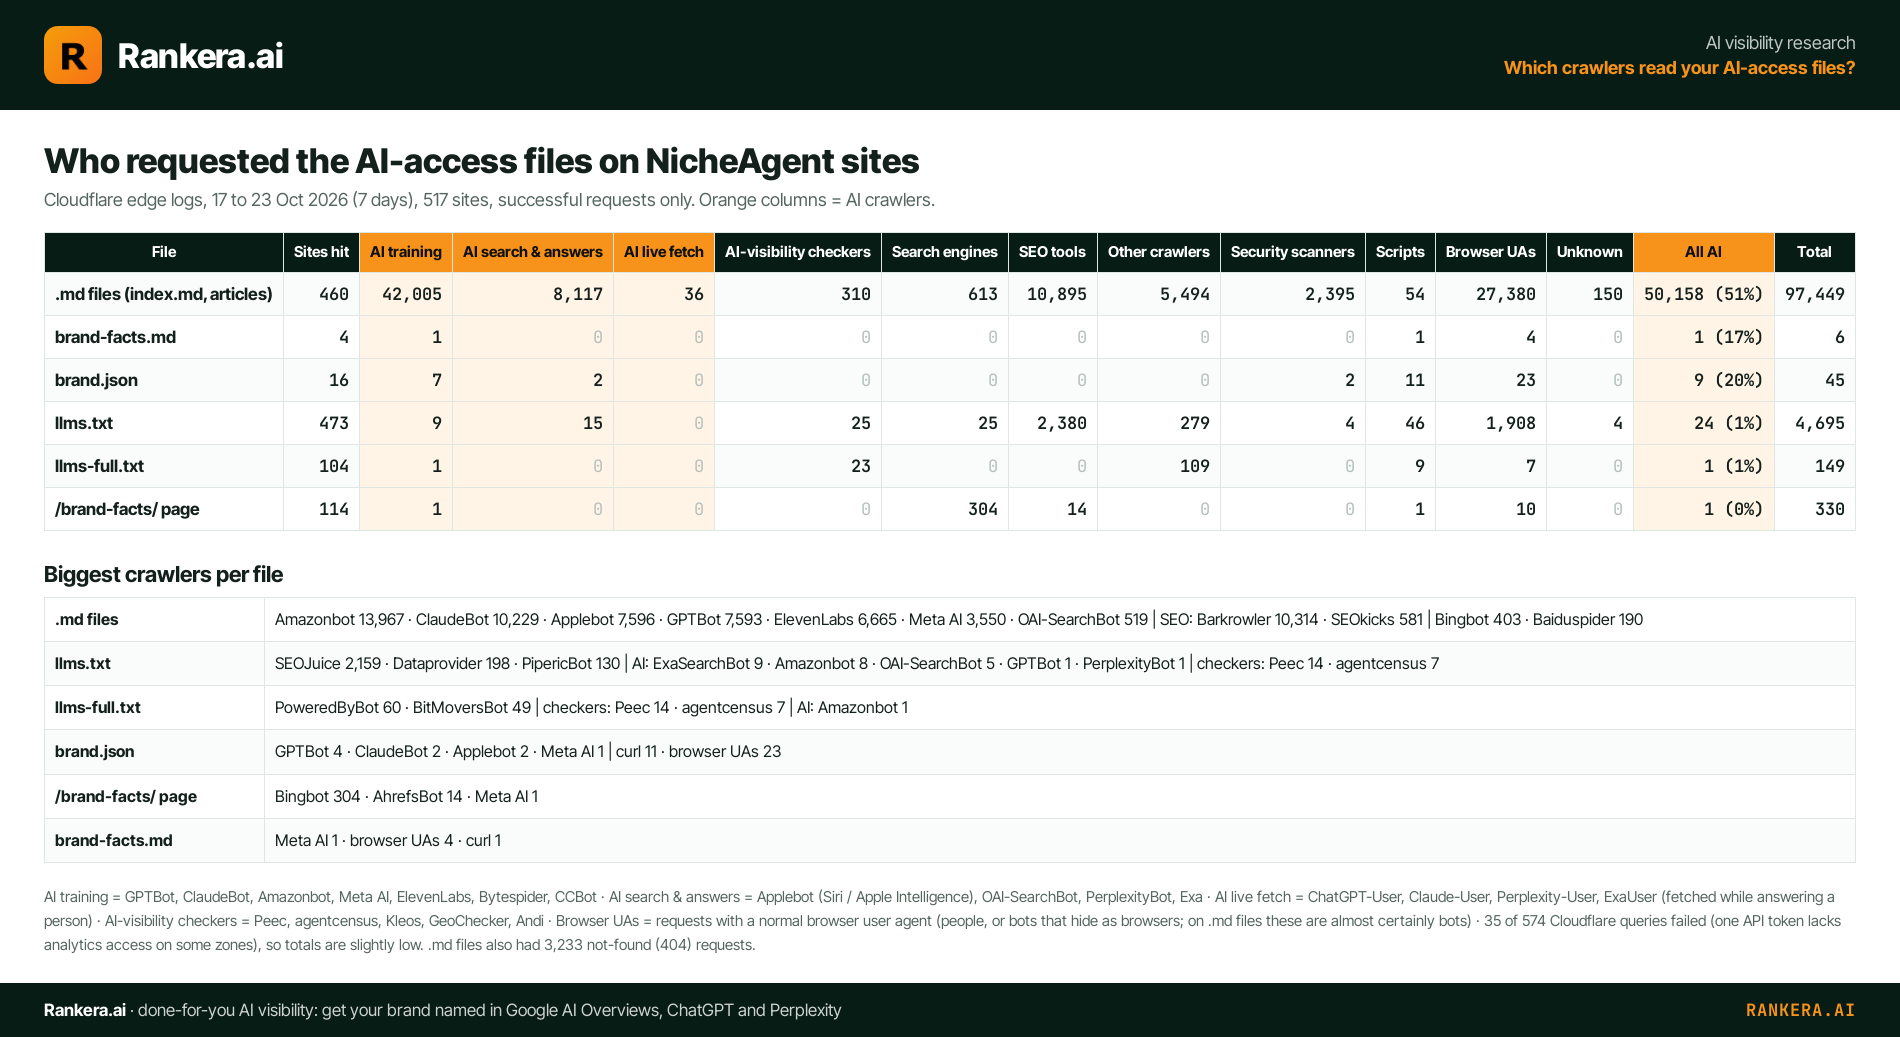
We logged every request for six AI-access files across 517 websites for a week: .md pages, llms.txt, llms-full.txt, brand.json, brand-facts.md and a /brand-facts/ page. AI crawlers asked for the .md files 50,158 times. They asked for llms.txt 24 times.
What we found
AI crawlers read .md files. llms.txt is read by tools.
1. .md files are what AI crawlers fetch
Half of all requests for the sites' Markdown pages (51%) came from AI crawlers: 42,005 from crawlers that collect training data (Amazonbot, ClaudeBot, GPTBot, Meta, ElevenLabs) and 8,117 from AI search crawlers (Applebot, OpenAI's OAI-SearchBot). They spread across 460 sites, and almost all of them were for inner pages: only 1,022 were for a home page's /index.md.
2. llms.txt is read by SEO tools, not AI crawlers
The llms.txt file was on 473 sites and got 4,695 requests, but only 24 came from AI crawlers. The biggest readers were SEO and marketing tools (2,380, mostly SEOJuice), visitors with ordinary browser user agents (1,908) and AI-visibility checkers such as Peec and agentcensus.
3. llms-full.txt got one AI request
The longer llms-full.txt was requested 149 times on 104 sites. One request came from an AI crawler (Amazonbot); most came from two small unidentified bots and AI-visibility checkers.
4. brand.json and brand-facts.md were barely touched
brand.json had 45 requests on 16 sites, 9 of them from AI crawlers (GPTBot 4, ClaudeBot 2, Applebot 2, Meta 1). brand-facts.md had 6 requests in total, one from an AI crawler.
5. The /brand-facts/ page is indexed by Bing, not AI
A normal web page of brand facts on 114 sites drew 330 requests: 304 from Bingbot, 14 from Ahrefs and one from an AI crawler. Search engines treat it like any other page.
6. Almost no live AI fetches
When ChatGPT, Claude or Perplexity open a page while answering someone, they use their own user agents (ChatGPT-User, Claude-User, Perplexity-User). None of them requested any of these files during the week. The only live fetches were 36 from Exa, all on .md pages.
| File | Sites | AI training | AI search & answers | AI live fetch | AI-visibility checkers | Search engines | SEO tools | Other crawlers | Security scanners | Scripts | Browser user agents | Unknown | All AI | Total |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| .md files (index.md, articles) | 460 | 42,005 | 8,117 | 36 | 310 | 613 | 10,895 | 5,494 | 2,395 | 54 | 27,380 | 150 | 50,158 (51%) | 97,449 |
| brand-facts.md | 4 | 1 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 1 | 4 | 0 | 1 (17%) | 6 |
| brand.json | 16 | 7 | 2 | 0 | 0 | 0 | 0 | 0 | 2 | 11 | 23 | 0 | 9 (20%) | 45 |
| llms.txt | 473 | 9 | 15 | 0 | 25 | 25 | 2,380 | 279 | 4 | 46 | 1,908 | 4 | 24 (1%) | 4,695 |
| llms-full.txt | 104 | 1 | 0 | 0 | 23 | 0 | 0 | 109 | 0 | 9 | 7 | 0 | 1 (1%) | 149 |
| /brand-facts/ page | 114 | 1 | 0 | 0 | 0 | 304 | 14 | 0 | 0 | 1 | 10 | 0 | 1 (0%) | 330 |
AI crawlers
Which AI crawlers read the .md files
Requests for .md files in the week, by crawler. Amazonbot, ClaudeBot, Applebot and GPTBot each made more than 7,500.
| Crawler | Company | What it does | Requests |
|---|---|---|---|
| Amazonbot | Amazon | Collects pages for Amazon's AI and Alexa | 13,967 |
| ClaudeBot | Anthropic | Collects pages for Claude models | 10,229 |
| Applebot | Apple | Feeds Siri, Spotlight and Apple Intelligence | 7,596 |
| GPTBot | OpenAI | Collects pages for ChatGPT models | 7,593 |
| ElevenLabs crawler | ElevenLabs | AI company crawler | 6,665 |
| Meta AI crawler | Meta | Collects pages for Meta AI (meta-externalagent) | 3,550 |
| OAI-SearchBot | OpenAI | Builds the index behind ChatGPT search | 519 |
What it means for your site
Make your pages easy for AI crawlers to read
- 1Serve clean Markdown versions of your pagesThe .md files drew about 2,000 times more AI crawler requests than llms.txt. Plain text with clear headings is what the crawlers came for.
- 2Keep llms.txt, but don't rely on itIt is cheap and some AI tools and agents check it, but on 473 sites it brought 24 AI crawler visits in a week.
- 3Put brand facts where crawlers already goFacts inside your pages are read; a separate brand.json or brand-facts file mostly isn't, yet.
A crawl is not a recommendation. Most of these requests came from crawlers that collect training data. Getting named in AI answers also depends on what the rest of the web says about your brand, which is what Rankera works on: see 10 live searches where Google's AI recommends our clients.
How we measured it
Cloudflare edge logs from 517 websites
We read Cloudflare's request logs for 517 content websites in our publishing network from 17 to 23 October 2026, keeping successful requests for six paths: any .md file, /brand.json, /llms.txt, /llms-full.txt, /brand-facts/ and /brand-facts.md. Each request was sorted by its user agent into AI crawlers (training, search and live fetches), AI-visibility checkers, search engines, SEO tools, security scanners, scripts and other crawlers. "Browser user agents" are requests that look like a normal browser; on .md files these are almost certainly bots. 35 of 574 log queries failed because one API token lacked analytics access, so the totals are slightly low. The .md files also had 3,233 requests for pages that did not exist.
What is llms.txt?
llms.txt is a plain text file at the root of a website (yoursite.com/llms.txt) that lists the site's most useful pages, written in Markdown, so that large language models and AI agents can find the right content quickly. llms-full.txt is a longer version that includes the full text of those pages in one file.
Do AI crawlers read llms.txt?
Very rarely, in our data. Across 473 websites that had an llms.txt file, AI crawlers requested it 24 times in 7 days, out of 4,695 requests in total. Most requests came from SEO tools such as SEOJuice and from AI-visibility checkers. The same AI crawlers made 50,158 requests for the sites' .md files in the same week.
What are .md files for AI crawlers?
A .md file is a Markdown version of a web page: the text and headings without the menus, scripts and styling. Our sites serve one for each page (for example /index.md). AI crawlers such as Amazonbot, ClaudeBot, GPTBot and Applebot requested these files more than any other AI-access file, and AI crawlers made 51% of all requests for them.
What is ClaudeBot?
ClaudeBot is Anthropic's web crawler. It collects public pages that may be used to train Claude models. In our logs it made 10,229 requests for .md files in one week, second only to Amazonbot.
Should I still add an llms.txt file?
It costs little and some AI tools and agents look for it, so there is no harm in having one. But in this data it did not attract AI crawlers, so it should not be the main way you make your content readable to AI. Clean, well-structured pages, ideally with Markdown versions, got far more AI crawler attention.
Does a crawl mean my brand gets recommended?
No. A crawl means an AI company fetched the page; most of these requests came from crawlers that collect training data. Being named in an AI answer also depends on what is written about your brand across the web, which is the part Rankera works on.
More case studies
More AI visibility case studies
Filmed in incognito: the AI names a brand we work with in each search and cites 20 of our videos.
Results · Autoblogging.aiFrom 48% to 70% of AI OverviewsHow YouTube videos lifted our own brand on 46 tracked buyer searches.
Research · 34,000 searchesHow Google AI Overviews choose sources30,613 AI Overviews and 243,714 citations across 10 countries and 17 industries.
Get your brand named in AI answers
Rankera is our done-for-you AI visibility service. Plans start at $250 a month for 20 keywords.
See plans →